הצייד והמכונה: גילוי חולשות ו-Bug Bounty בעזרת AI Agents
DigitalWhisper #191: practical AI-assisted security research, variant hunting, authorization testing, and validating findings before reporting them. Full article in Hebrew (PDF).
Writing
Notes on AI, software, security, and what happens when the experiment does not go to plan. English and Hebrew.
28 items
DigitalWhisper #191: practical AI-assisted security research, variant hunting, authorization testing, and validating findings before reporting them. Full article in Hebrew (PDF).

A playful exploration of steering a small language model through its internal activations.

A personal essay about keeping your judgment and curiosity while building with AI.

The story behind contributing boundary checks to upstream Linux Wi-Fi drivers.

A closer look at permissions and the authority they grant to agents.

An agent experiment involving a game, its rules, and some unexpected behavior.

A prompt-injection experiment with published fixtures, scoring, and results.

Building a browser tool that uses on-device AI to help make sense of a feed.
Coauthored with Mike Erlihson. A Hebrew review of NLP methods for grouping fragmented Qumran scrolls, combining semantic representations with statistical language features.

Comparing open models on a software-security benchmark.

How inbound and outbound attachment filenames crossed NanoClaw’s host-side file boundaries, and how the maintainer fixed both paths.

An exploration of how we represent and work with text.

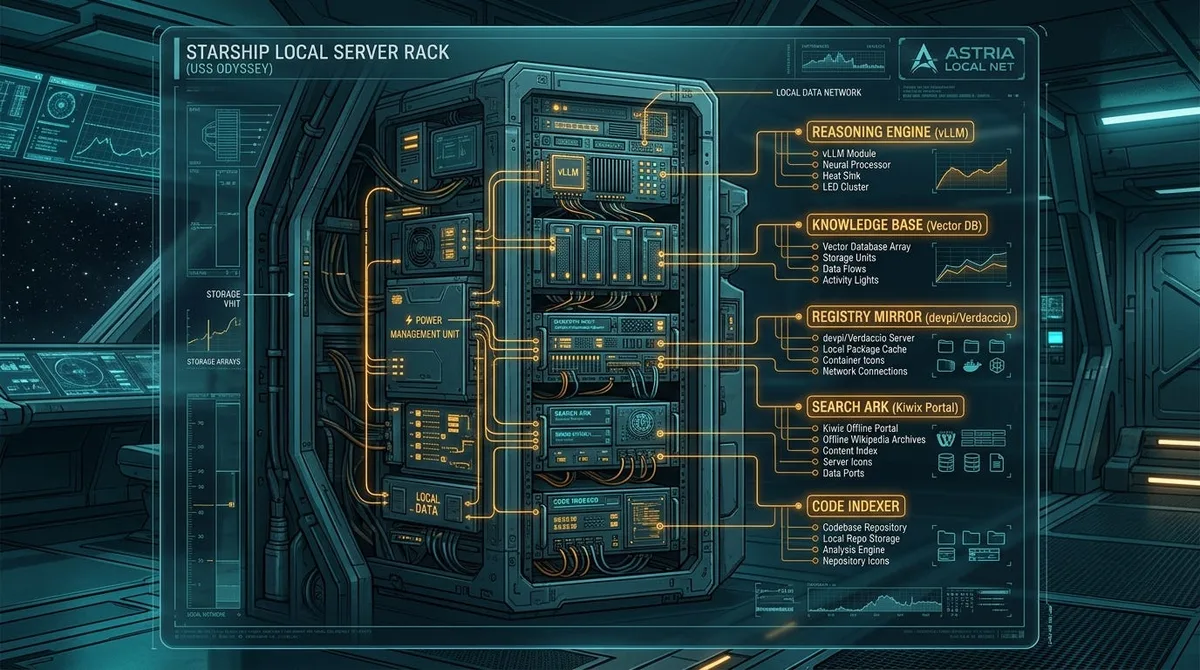
Exploring the engineering choices behind an offline AI coding environment.

Lessons and connections from vulnerability research.
Coauthored with Mike Erlihson. A Hebrew review asking whether AI can stand in for developers in software-engineering user studies, and what that means for reliable evidence.
A first-person account of researching server-side request forgery.
Coauthored with Mike Erlihson. The Hebrew review of SkillsBench: when agent skills help, hurt, or add noise.

Coauthored with Mike Erlihson for Mathy AI. A review of SkillsBench and when agent skills help, hurt, or add noise.

The build story behind Substack Network, a Chrome extension for visualizing recommendation connections.

DAP-based debugging tools for AI coding agents: breakpoints, runtime state, and practical limitations.

AI code is exploding, but "Vibe Merging" is breaking production. A deep dive into the first neutral benchmark for Code Review agents: CodeRabbit, Cursor, Baz.

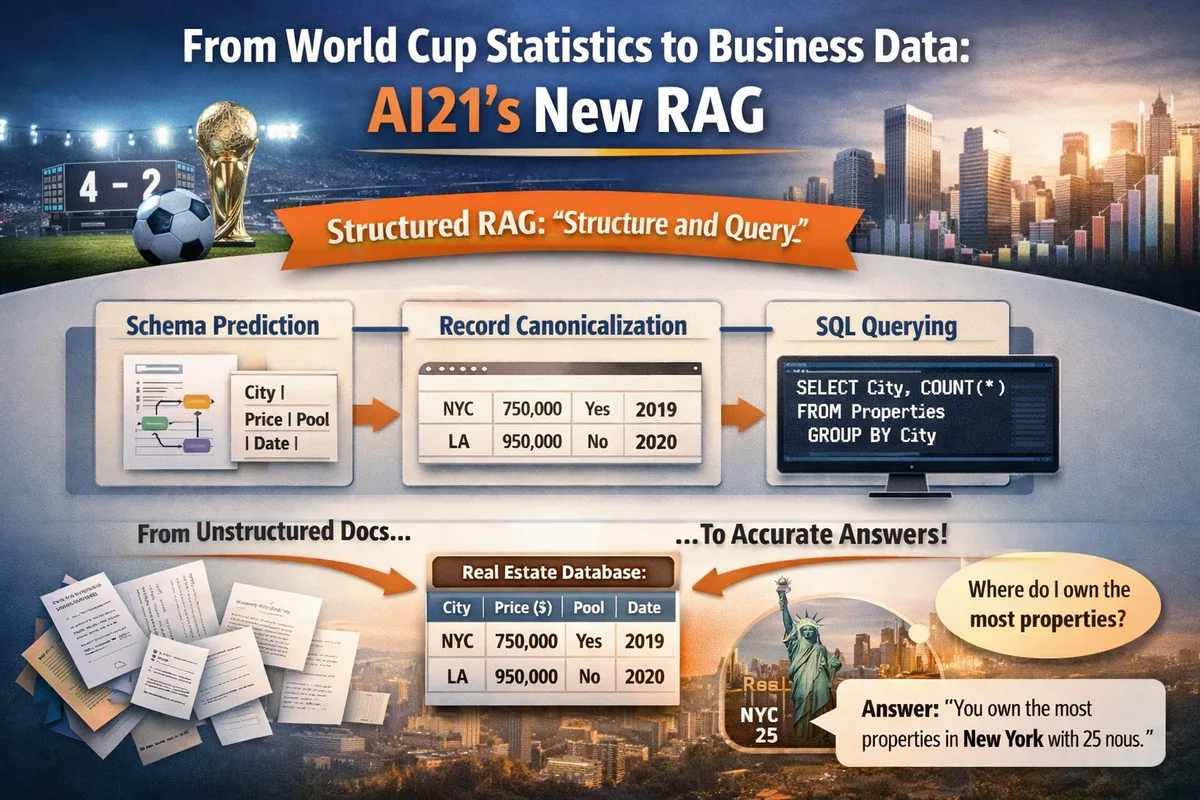
Coauthored with Mike Erlihson for Mathy AI. A hands-on review of Structured RAG for aggregative questions, with a reconstructed Colab implementation.

From LLMs to MCP and Skills: Understand the simple concepts powering Cursor, Windsurf, Copilot and Claude Code.

Discover why BERT and ModernBERT remain essential in 2026. Learn how encoders beat generative LLMs in latency, cost, and precision for production NLP tasks.
An explanation of temperature and sampling methods, published as a guest article at Decoding AI.

A practical introduction to HumanEval, with lessons from our TAU course project generating new programming exercises.

Practical intro to adversarial ML. See how FGSM fools neural networks.

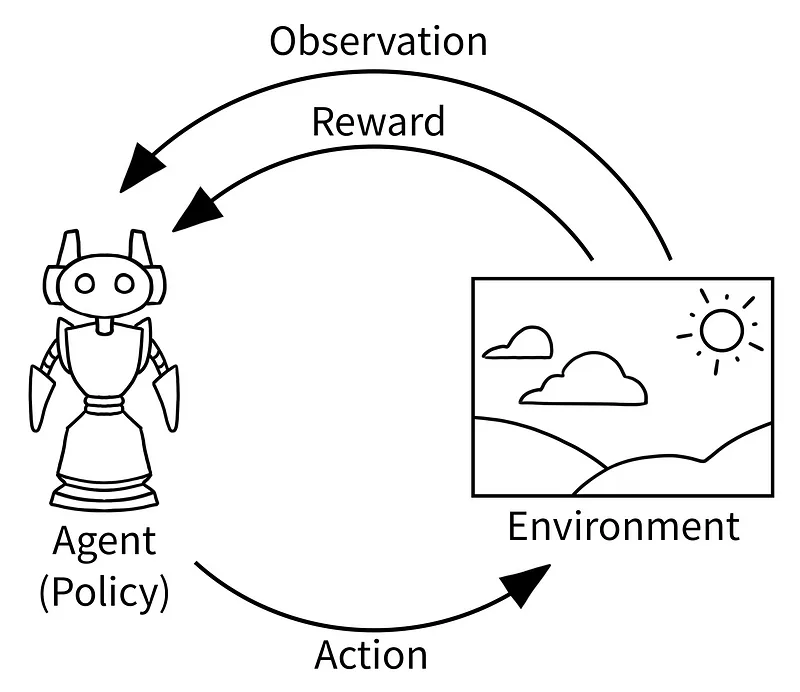
A practical reinforcement-learning tutorial using Gymnasium and CliffWalking.
Try another word, or reset the filters.